

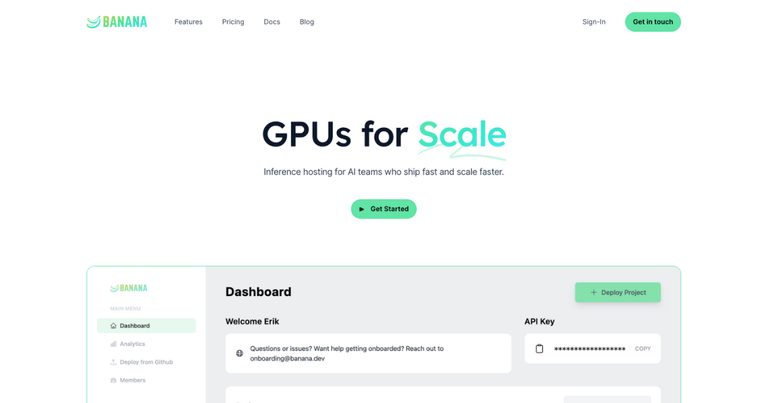
Banana provides GPU inference hosting for AI teams, focusing on speed and scalability with features like autoscaling and transparent pricing.
Features
- Autoscaling GPU Infrastructure — Banana automatically scales GPU replicas up and down based on demand, keeping costs low while maintaining high performance for inference workloads. This eliminates the need for manual capacity planning and ensures resources match actual usage patterns.
- Transparent Pass-Through Pricing — Unlike competitors who add significant margins on GPU time, Banana charges a flat monthly fee plus the actual cost of compute at market rates. This zero-markup model means teams pay only for what they use without hidden fees or inflated GPU costs.
- Integrated DevOps Platform — A complete development experience with GitHub integration, CI/CD pipelines, CLI tools, rolling deployments, distributed tracing, and centralized logging. Teams can manage their entire ML deployment workflow from a single platform without stitching together multiple tools.
- Real-Time Observability & Analytics — Built-in performance monitoring for viewing request traffic, latency metrics, and error rates in real-time. Includes business analytics for tracking spend, monitoring endpoint usage over time, and understanding customer behavior patterns.
- Open Automation API — An extensible API with official SDKs and CLI that allows teams to automate deployments and integrate Banana into existing workflows. The open architecture prevents vendor lock-in and enables custom automation pipelines.
- Potassium Framework — An open-source HTTP framework that lets developers write backend inference services in Python with a simple, intuitive API. Supports popular ML libraries like Hugging Face Transformers and provides a standardized way to package and deploy models.
Use Cases
Production ML Model Serving
AI teams deploying machine learning models to production who need reliable, scalable GPU inference infrastructure. Banana handles the complexity of GPU provisioning, load balancing, and autoscaling so developers can focus on model quality rather than infrastructure management. Target Audience: ML engineers and AI startups shipping inference-heavy applications like NLP models, image generation, or recommendation systems
High-Throughput API Endpoints
Companies building customer-facing AI features that require low-latency, high-availability GPU inference at scale. Banana's autoscaling ensures consistent performance during traffic spikes while pass-through pricing keeps costs predictable as usage grows. Target Audience: Product teams and backend engineers at SaaS companies integrating AI capabilities into their applications
Rapid Prototyping to Production Pipeline
Development teams that need to quickly iterate on ML models and deploy them to production with minimal DevOps overhead. The integrated CI/CD, GitHub integration, and branch deployments enable a smooth transition from experimentation to production-ready services. Target Audience: Data scientists and ML developers who want to move from Jupyter notebooks to deployed APIs without deep infrastructure expertise
Cost-Optimized GPU Workloads
Organizations running variable-load inference workloads where GPU utilization fluctuates throughout the day. Banana's autoscaling and transparent pricing help avoid paying for idle GPU capacity while ensuring resources are available during peak demand. Target Audience: Engineering leaders and DevOps teams managing GPU budgets who need visibility into compute costs and utilization metrics
Pros
- Zero-markup pricing model eliminates vendor margin on GPU compute, potentially offering significant cost savings compared to competitors like AWS SageMaker or Google Cloud AI who charge premiums on top of hardware costs
- Comprehensive DevOps tooling reduces the need to integrate multiple platforms, saving engineering time on CI/CD setup, monitoring configuration, and deployment automation
- Open-source Potassium framework provides flexibility and prevents vendor lock-in, allowing teams to migrate workloads if needed while maintaining code portability
- Real-time observability with built-in performance monitoring, business analytics, and debugging tools provides visibility into both technical performance and cost metrics without third-party tools
- Autoscaling capabilities handle traffic spikes automatically, reducing the risk of downtime or degraded performance during high-demand periods while minimizing costs during low-traffic periods
Cons
- The product appears to be sunsetting or discontinuing service, as indicated by the 'Sunset' notice on the website, making it unsuitable for new long-term production deployments
- Base pricing starts at $1,200/month for the Team plan, which may be prohibitive for individual developers, small startups, or teams with limited budgets exploring AI inference
- Platform is specifically designed for inference workloads only and does not support model training, requiring teams to use separate infrastructure for the training phase of ML development
- Limited to GPU-based workloads, which may not be cost-effective for models that can run efficiently on CPU or for lightweight inference tasks that don't require GPU acceleration


