Airy - Open Source Data Platform
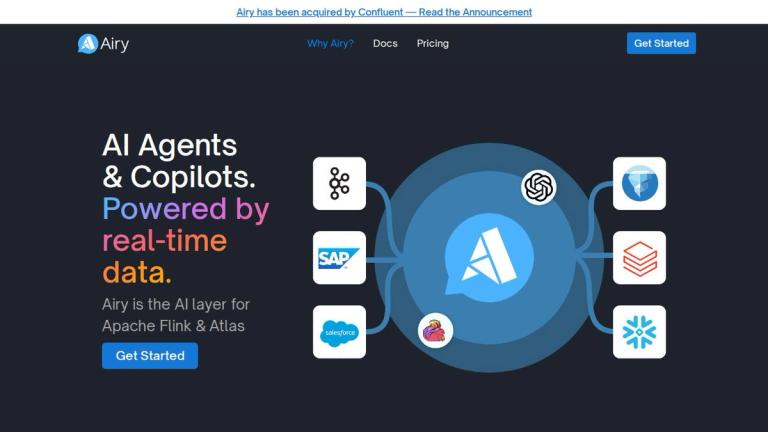
Airy is an open-source data platform that positions itself as the AI layer for Apache Flink & Atlas. It empowers developers and enterprises to build real-time data pipelines and make data universally accessible for AI Agents and Copilots.
Core Capabilities
Airy enables stream processing that bridges operational systems and analytics by orchestrating real-time jobs. By combining live Kafka streams with historical data in open formats, AI Agents powered by Airy stay grounded, responsive, and deeply intelligent.
The platform supports Multi-Agent AI Systems powered by Event-Driven Architecture, allowing AI Agents to understand enterprise data through AI-generated and indexed metadata. These agents run continuously to detect complex patterns of events in real-time data from business-critical systems.
Key Differentiators
- Complex Event Processing: Simplified with Apache Flink integration
- Data Governance: Built-in lineage tracking and data governance for AI systems
- AI Assistants: Natural language interface for business users to interact with complex datasets
- Prebuilt Connectors: Seamless integration with data sources, foundation models, and vector databases
Enterprise Partnerships
Airy partners with major cloud and technology providers including AWS, Microsoft Azure, Salesforce, Nvidia, Meta, Confluent, and Google Cloud, demonstrating strong enterprise credibility and integration capabilities.
Target Audience
Enterprise developers, data engineers, AI/ML teams, and organizations building real-time AI agent systems
Key Features
- Real-time data pipeline construction
- AI Agent orchestration with stream processing
- Apache Flink integration for complex event processing
- Data lineage and governance for AI systems
- Multi-Agent AI Systems with event-driven architecture
- Natural language AI Assistants for business users
- Prebuilt connectors for data sources, foundation models & vector databases
- Metadata generation and semantic understanding
- Continuous pattern detection in real-time data streams
- Integration with Kafka streams and historical data
Use Cases
- Building real-time data pipelines for enterprise systems
- Deploying AI Agents for operational monitoring and alerting
- Enabling self-serve AI/BI for business users
- Detecting complex event patterns in streaming data
- Implementing data governance and lineage tracking for AI
- Creating multi-agent systems for enterprise automation
- Connecting disparate data sources with prebuilt connectors
- Triggering automated actions based on real-time data events
Pros
- Open source platform with enterprise-grade capabilities
- Strong partnerships with major cloud providers (AWS, Azure, Google Cloud)
- Native Apache Flink integration for powerful stream processing
- Comprehensive data governance and lineage features
- Supports both foundation models and custom AI models
- Event-driven architecture enables real-time responsiveness
Cons
- May require technical expertise for setup and configuration
- Complex architecture may have a learning curve for new users
Pricing
Open source with enterprise options available (contact for pricing)