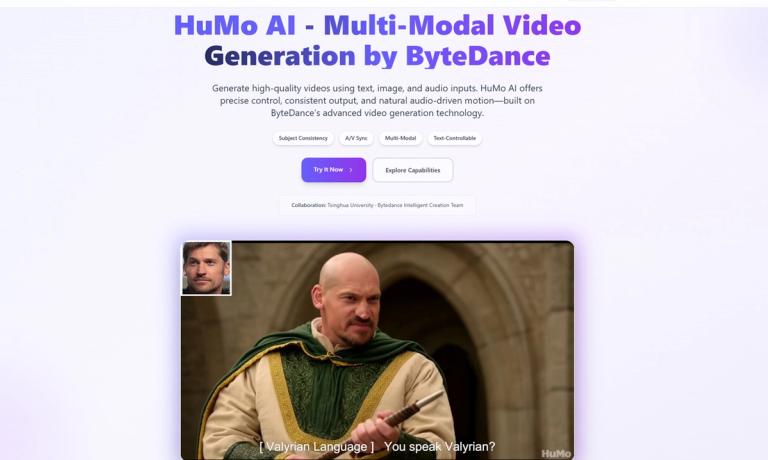
HuMo AI by ByteDance creates high-quality human videos from text, image, and audio inputs, offering precise control and natural audio-driven motion.
Features
- Multi-Modal Input Conditioning — HuMo AI supports four flexible generation modes—Text (T), Text+Image (TI), Text+Audio (TA), and Text+Image+Audio (TIA)—allowing creators to combine text prompts, reference images, and audio clips for precise, layered video generation with maximum creative control.
- Subject Consistency & Identity Preservation — Maintains consistent character identity across generated videos, preserving facial features, body structure, and recognizable appearance even when changing outfits, hairstyles, accessories, or scenes via different text prompts.
- Audio-Driven Lip-Sync & Motion — Generates accurate lip synchronization, natural facial expressions, and body motion aligned with audio input signals—ideal for dialogue scenes, singing, narration, and voice-driven character animation.
- Text-Controllable Editing — Enables real-time appearance and scene modifications through text prompts while keeping the same subject identity stable, supporting outfit swaps, hairstyle changes, accessory additions, and background alterations.
- Cloud-Based Processing — Runs entirely on server-side hardware with no need for a local high-VRAM GPU, making high-quality AI video generation accessible to users without expensive computing infrastructure.
- Commercial Use Licensing — All pricing tiers include a commercial use license, enabling businesses and creators to use generated videos for marketing, branded content, product demos, and professional projects.
Use Cases
Digital Humans & Virtual Avatars
Create expressive, identity-consistent digital humans from text descriptions, reference images, and audio inputs. HuMo AI's audio-driven motion and lip-sync capabilities make it ideal for building virtual influencers, interactive AI characters, and digital spokespersons that maintain consistent appearance across multiple video outputs. Target Audience: Virtual influencer creators, AI character developers, metaverse builders, and brands seeking digital brand ambassadors
Lip-Sync & Voice-Driven Animation
Generate accurate lip-sync and expressive speech animation directly from audio inputs. Perfect for producing dialogue-heavy videos, dubbing existing content, creating voiceovers, and building conversational AI interfaces where natural mouth movements and facial expressions sync precisely with speech. Target Audience: Film and animation studios, dubbing professionals, podcast creators, e-learning developers, and conversational AI companies
Marketing & Social Media Content Production
Create customized marketing clips and social media videos with controlled visual style and fast turnaround. Combine text prompts, brand imagery, and audio to scale branded content production without traditional filming, enabling rapid A/B testing of creative concepts and personalized video ads. Target Audience: Digital marketers, social media managers, advertising agencies, e-commerce brands, and content creators seeking scalable video production
Education & Training Content Creation
Generate clear, engaging teaching and training videos without physical filming. HuMo AI's text-to-video and audio-driven motion capabilities support explainer videos, language-learning content, corporate training modules, and instructional materials with natural presenter-like delivery. Target Audience: Educators, corporate trainers, e-learning platforms, language learning apps, and instructional designers
Pros
- True multi-modal conditioning (text + image + audio) provides significantly more creative control than text-only video generators, enabling complex scene composition with consistent subjects and synchronized audio.
- Industry-leading subject consistency preserves character identity across outfit changes, scene transitions, and multiple video generations—critical for branded content and character-driven storytelling.
- Accurate audio-visual synchronization with natural lip-sync, facial expressions, and body motion driven by audio inputs eliminates the need for separate animation or lip-sync tools.
- Cloud-based architecture requires no local GPU hardware, making professional-grade AI video generation accessible to individual creators and small teams without expensive computing setups.
- Flexible one-time credit pricing model with commercial use licenses across all tiers allows businesses to scale usage without recurring subscription commitments.
Cons
- Currently limited to short-form video generation only—resolution and duration vary by mode and deployment, restricting use for long-form content production or full-length video projects.
- Credit-based consumption model means heavy users may need to purchase multiple packages, and costs can accumulate quickly for large-scale video production workflows.
- Output quality and capabilities depend on input quality—low-resolution images or noisy audio can degrade identity consistency and lip-sync accuracy, requiring careful input preparation.
- Not fully open-source at the product level; while research components may be available, commercial deployments and advanced features are tied to the hosted platform, limiting self-hosted customization options.