

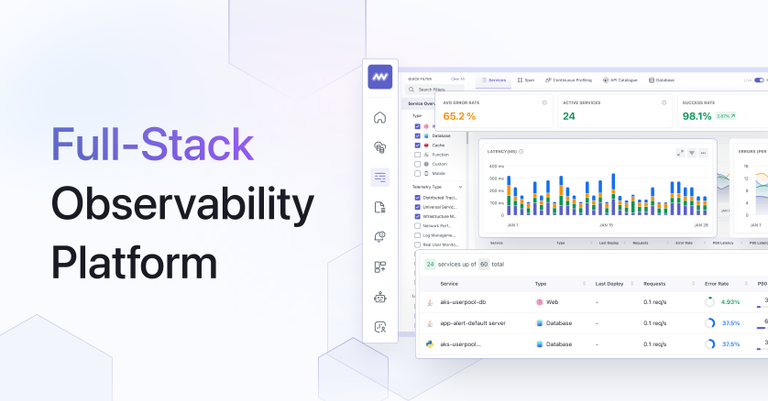
Middleware offers full-stack observability with real-time monitoring and diagnostics, helping teams detect issues at scale while keeping data secure.
Features
- OpsAI - AI-Powered SRE Agent — An intelligent AI agent that automatically detects and resolves production issues before they reach users. It analyzes data from APM traces, real-user monitoring (RUM), and logs to pinpoint root causes and fix problems across any platform or programming language with smart contextual understanding.
- Unified Full-Stack Observability — Consolidates metrics, logs, traces, events, and real-user monitoring onto a single unified timeline in real-time. Provides complete visibility from frontend to backend, enabling teams to connect causation to correlation and resolve issues end-to-end.
- One-Command Installation with OpenTelemetry — Deploys in minutes using a single command with an OpenTelemetry-based agent. Supports monitoring of entire tech stacks including infrastructure, applications, databases, containers, serverless functions, and LLM observability without complex configuration.
- 200+ Pre-Built Integrations — Seamlessly adapts to existing technology ecosystems with over 200 integrations spanning major cloud platforms (AWS, Azure, GCP), Kubernetes environments, and popular DevOps tools. Designed to work within your current infrastructure, not replace it.
- Enterprise-Grade Security & Compliance — Data encrypted both in transit and at rest, adhering to industry standards including HIPAA, GDPR, and SOC 2 Type II. Offers on-premise deployment options and bring-your-own-cloud flexibility for organizations with strict data governance requirements.
- Comprehensive Monitoring Suite — Includes specialized monitoring capabilities: Infrastructure Monitoring, APM, Log Monitoring, Real User Monitoring (RUM), Synthetic Monitoring, Database Monitoring, Container Monitoring, Browser Testing, and LLM Observability—all accessible from a single platform.
Use Cases
Proactive Incident Resolution for SRE Teams
Site Reliability Engineering teams leverage OpsAI to automatically detect anomalies across distributed systems, identify root causes in frontend or backend code, and resolve up to 70% of issues automatically—reducing mean time to resolution by 90% and preventing user-facing outages. Target Audience: SRE teams, DevOps engineers, and platform engineers managing production environments at scale
Cloud Infrastructure Monitoring for Multi-Cloud Environments
Organizations running workloads across AWS, Google Cloud Platform, Microsoft Azure, and Kubernetes clusters use Middleware to gain a unified view of their entire cloud infrastructure. Teams monitor performance, track costs, and ensure uptime across all cloud providers from a single dashboard. Target Audience: Cloud architects, infrastructure teams, and IT operations managing multi-cloud or hybrid cloud deployments
Digital Experience Monitoring for E-Commerce & Retail
Retail and commerce companies monitor real user sessions, track frontend performance, and correlate browser-side issues with backend services. Synthetic monitoring ensures critical user journeys (checkout, search, product pages) remain performant before and during peak traffic events like sales or product launches. Target Audience: E-commerce platforms, retail technology teams, and digital experience managers focused on customer-facing application performance
Application Performance Optimization for Development Teams
Development teams use distributed tracing and APM to identify performance bottlenecks, slow database queries, and code-level issues across microservices architectures. The unified timeline connects logs, traces, and metrics to accelerate debugging and improve developer productivity by up to 80%. Target Audience: Software developers, engineering managers, and backend/frontend teams building and maintaining complex distributed applications
Pros
- AI-driven automation resolves up to 70% of production issues automatically, significantly reducing manual intervention and on-call burden for engineering teams.
- Dramatically faster incident resolution with 90% reduction in time-to-resolution through intelligent root cause analysis across frontend and backend systems.
- True full-stack observability in a single platform—combines APM, infrastructure monitoring, logs, RUM, synthetic monitoring, database monitoring, and LLM observability without needing multiple tools.
- Rapid deployment with one-command OpenTelemetry-based installation that gets teams from zero to full observability in minutes rather than days or weeks.
- Enterprise-ready with flexible deployment options (on-premise, bring-your-own-cloud), strong security compliance (HIPAA, GDPR, SOC 2 Type II), and 24/7 global customer support.
Cons
- AI-driven automation may require initial tuning and training period to achieve optimal accuracy for specific environments, potentially requiring manual oversight during onboarding.
- As a comprehensive full-stack platform, teams with simple monitoring needs may find the breadth of features overwhelming and face a steeper learning curve to leverage all capabilities effectively.
- Heavy reliance on the Middleware ecosystem for unified observability could create vendor lock-in, making future migration to alternative platforms more complex.
- Pricing transparency is limited on the website—enterprise-focused features like on-premise deployment and advanced AI capabilities may come at premium tiers not clearly communicated upfront.


