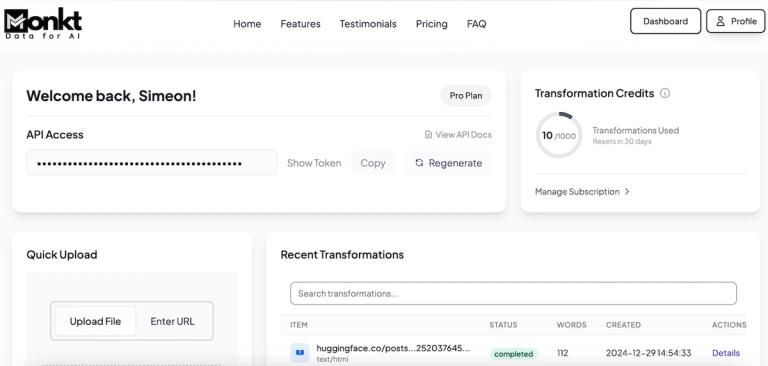
Transform documents into AI-ready Markdown or structured JSON for AI/LLM systems, supporting various formats and custom schemas.
Features
- Universal Document Format Support — Process 10+ document formats including PDF, Word (.docx/.doc), PowerPoint (.pptx/.ppt), Excel (.xlsx/.xls), CSV, images (JPG, PNG, WebP), and raw HTML/web pages. The system intelligently understands document structure and preserves formatting integrity during conversion.
- Dual Output: Clean Markdown & Structured JSON — Export documents as clean, standardized Markdown optimized for AI/LLM systems, or transform them into structured JSON using automated schema detection or fully custom schema definitions for precise data extraction tailored to your specific needs.
- DeepExtract™ AI Processing — Advanced AI-powered processing that extracts and understands images within documents, converts visual content into descriptive text, identifies key information, metadata, and semantic relationships. Includes OCR for scanned documents and page layout/reading order understanding.
- LLM-Optimized Output Formatting — Output formats specifically optimized for popular Large Language Model systems, ensuring data is ready for AI processing without additional formatting. Perfect for RAG pipelines, fine-tuning datasets, and AI chatbot knowledge bases.
- Batch Processing & Smart Caching — Process multiple documents simultaneously for large-scale data transformation. Smart caching system optimizes transformation usage by serving repeated conversions from cache, with cache duration matching your plan's data persistence period.
- REST API Integration — Seamlessly integrate document processing into applications with a comprehensive REST API. Transform content programmatically and automate document workflows at scale with custom integration support available for Enterprise plans.
Use Cases
AI Chatbot & Knowledge Base Creation
Transform documentation, knowledge bases, or entire websites into intelligent chatbots and smart search systems. The structured output integrates seamlessly with LLMs to create context-aware AI assistants with semantic understanding of your content, enabling advanced query understanding and intelligent content discovery. Target Audience: AI developers, product teams, and customer support departments building conversational AI solutions
LLM Training Dataset Preparation
Create high-quality, clean training datasets for fine-tuning Large Language Models. Convert research papers, technical documents, and domain-specific content into consistent, structured formats. The intelligent chunking and vectorization features prepare RAG-optimized data for specialized AI model training. Target Audience: ML engineers, data scientists, and AI researchers preparing training data for custom LLM models
Personal Knowledge Management (PKM)
Convert PDFs, web pages, research papers, and other formats into clean, Obsidian-compatible Markdown for personal knowledge bases. Automatically extract and describe figures from documents, making it easy to build interconnected note systems from diverse document sources. Target Audience: Knowledge workers, researchers, students, and Obsidian/Notion enthusiasts managing personal knowledge systems
Automated Document Data Extraction
Extract structured data from invoices, articles, reports, and business documents using custom JSON schemas. Automate data pipelines by converting unstructured documents into deterministic JSON output, enabling seamless integration with existing ML pipelines and business intelligence systems. Target Audience: Business analysts, operations teams, and enterprises automating document processing workflows at scale
Pros
- Comprehensive format support (10+ formats) with intelligent structure preservation, handling everything from PDFs and Office documents to images and web pages in a single platform
- Flexible output options with both clean Markdown and structured JSON, including custom schema definitions for precise, deterministic data extraction tailored to specific use cases
- AI-native design with LLM-optimized outputs, DeepExtract™ processing, image understanding, and OCR capabilities that make documents immediately usable for RAG pipelines and AI training
- Scalable processing with batch capabilities, smart caching that saves transformation credits, and API integration for automated workflows—processing over 1M documents for 7K+ users
- Accessible entry point at $4.99/month with a free tier available, plus enterprise-grade options including GPU-accelerated inference and dedicated project management
Cons
- File size limitations vary by plan (5MB for free/Start, 25MB for Pro), which may restrict processing of large documents like lengthy research papers or complex multi-page PDFs
- Monthly transformation quotas (50 for Start, 1,000 for Pro) can be limiting for high-volume users, requiring careful usage planning or upgrading to higher-tier plans
- Advanced features like DeepExtract™ processing, OCR for scanned documents, and page layout understanding are locked behind Pro and Enterprise tiers, limiting capabilities for budget-conscious users
- Upcoming format support (MP3, MP4, WAV) is not yet available, meaning multimedia content processing is currently unavailable despite being listed as coming soon